Define service availability, actionable alerts, detection, restoration, and operational risk with formulas, worked examples, and a weekly review plan. Use this guide with your operations team to identify one improvement, assign an owner, and verify the result.
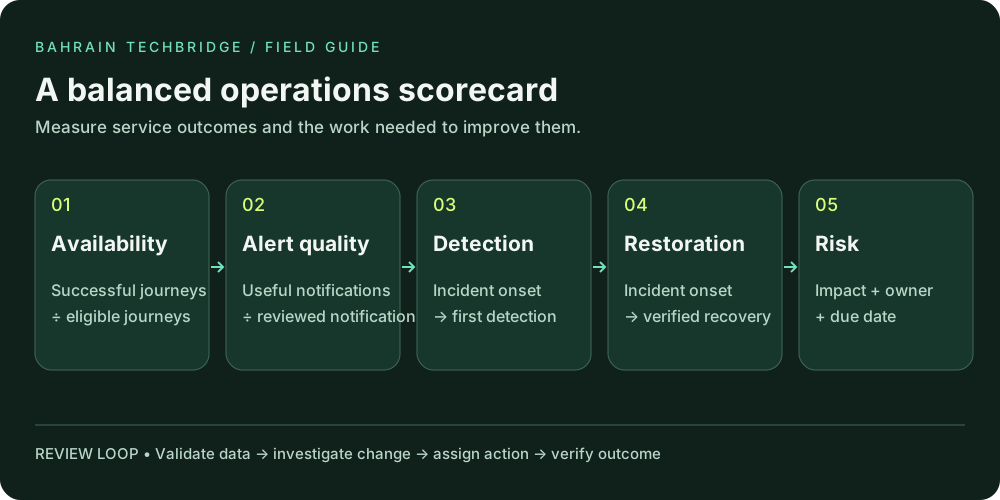
Define the measurement before building the chart
A useful operations report should help a service owner make a decision: investigate a customer journey, improve an escalation path, or fund a recurring reliability fix. A wall of green servers cannot answer those questions by itself. Begin with a small set of measures that connect technical signals to service outcomes, then agree how each number is calculated.
Choose one critical service for the first iteration. Write down its users, operating hours, dependencies, support owner, and the transactions that must succeed. Define a service-level indicator (SLI), which is the measurement, and a service-level objective (SLO), which is the target over an agreed period. Keep contractual service-level agreements (SLAs) separate: they may use different exclusions or reporting rules.
For every metric, record the source, reporting window, timezone, denominator, exclusions, and person responsible for investigating changes. Missing telemetry must be visible. If monitoring stopped for two hours, an uninterrupted green line is not proof that the service was available. Show the gap and explain its effect on the report.
1. Service availability: measure the journey
For a request-based indicator, calculate availability as successful eligible requests divided by all eligible requests, multiplied by 100. Define success carefully. An HTTP 200 response that contains an application error may still represent a failed customer transaction. Consider an independent synthetic journey to detect failures when request volume falls or a service cannot be reached.
For a time-based indicator, use available eligible minutes divided by total eligible minutes. Do not mix request-based and time-based percentages in the same trend without labeling them. Agree how planned maintenance is treated before the reporting period begins, and show excluded maintenance separately so operational impact remains visible.
A 30-day service window contains 43,200 minutes. With 18 unavailable minutes, time-based availability is (43,200 − 18) ÷ 43,200 × 100 = 99.9583%. At a 99.9% objective, the period allows 43.2 unavailable minutes; 25.2 minutes remain. This calculation assumes no exclusions.
Separate customer channels and important regions where failure patterns differ. A busy healthy endpoint can hide a failing low-volume payment operation inside an overall average. Assign an owner to any indicator that falls below its objective, and investigate whether the cause was a service failure, a measurement defect, or both.
2. Alert quality: count the work, not just the noise
Alert volume shows demand on the team; it does not establish whether monitoring is effective. Review a sample of notifications and classify each as actionable, duplicate, informational, or incorrect. Use a written rule for classification so two analysts reach comparable conclusions. An actionable alert prompts a meaningful investigation or response, even if the investigation eventually finds no customer impact.
Track actionable notifications divided by reviewed notifications. Also track interruptions per shift and repeated notifications per incident. Avoid calling every alert without an incident ticket a false positive: some valid capacity warnings lead to preventive work, while some tickets are created automatically and never investigated.
Suppose 200 reviewed notifications include 70 actionable events, 80 duplicates, 35 informational items, and 15 incorrect signals. Actionability is 35%; incorrect signals are 7.5%. Those percentages answer different questions. Consolidating duplicates may improve focus without changing detection coverage. Turning off the entire monitor might reduce volume while concealing the next real failure.
Record the tuning change, affected service, reviewer, rollback method, and observation period. Check missed incidents and customer-reported failures alongside any reduction in alerts. A quieter console is only valuable if the team continues to catch important problems.
3. MTTD: make the start time defensible
Mean time to detect (MTTD) is the average interval between the agreed incident onset and detection. Define onset using the earliest credible evidence of service degradation, and detection using the first qualifying signal received by operations. A ticket creation timestamp may be convenient, but it is not always the moment the service failed or the moment someone noticed.
For each incident, preserve the evidence behind both timestamps. If onset is uncertain, mark it as estimated and report that uncertainty rather than inventing precision. Keep customer-detected and monitoring-detected incidents distinguishable. This helps reveal gaps in monitoring coverage and differences in the speed of detection.
Compare similar incidents by service and severity. Report the sample size, median, and a high percentile when the sample supports it, alongside the mean. One unusually long incident can move an average sharply; a month with only two incidents cannot support strong claims about long-term improvement. Inspect the individual cases before changing targets.
4. MTTR: specify what recovery means
MTTR is used for several different phrases. In this guide it means mean time to restore service, measured from the agreed incident onset to verified restoration. Other organizations start at detection; either convention can be useful if it is explicit and applied consistently. Never compare teams using different start points as though the results are equivalent.
Record acknowledgement, mitigation start, and restoration as separate timestamps. These reveal whether delay came from routing, diagnosis, change approval, recovery execution, or validation. Restoration means the affected customer journey works again; it does not require every long-term corrective action to be complete.
In a hypothetical incident, degradation starts at 09:02, monitoring detects it at 09:06, an owner acknowledges at 09:09, and service is verified restored at 09:38. Detection took four minutes, acknowledgement took three minutes after detection, and restoration took 36 minutes from onset. The same record can therefore support several useful measures without relabeling them.
Review recurring long restoration intervals with the involved teams. A runbook improvement may help one failure mode; a dependency redesign may be needed for another. Use the metric to locate friction, not to pressure responders into declaring recovery before verification is complete.
5. Operational risk: turn the backlog into commitments
Track open monitoring gaps, recurring failures, expiring certificates, capacity concerns, and overdue resilience work. A raw item count has limited meaning because one unmonitored critical dependency may matter more than dozens of low-impact improvements. Add affected service, possible impact, accountable owner, due date, mitigation, and the evidence required for closure.
Review items by severity and age. Distinguish accepted risk from forgotten work, and record when an acceptance must be reconsidered. “Waiting for another team” is a status, not an owner. Someone still needs to coordinate the next decision and communicate exposure to the service owner.
| Measure | Question to ask | Practical next action |
|---|---|---|
| Availability | Which journey is failing? | Investigate the affected segment. |
| Alert quality | Which notifications create no useful work? | Review and tune one noisy rule. |
| MTTD | Why did detection arrive late? | Add or repair a coverage check. |
| MTTR | Where did restoration stall? | Improve the slowest response step. |
| Operational risk | Which exposure has no credible plan? | Assign an owner and decision date. |
Run a weekly review that ends in action
Use a short, repeatable meeting with the service owner and operational leads. First check data completeness. Next review objective breaches, missed detections, and the incidents that took longest to restore. Then select a small number of changes that the team can complete before the next review. Give each change a named owner and a measurable acceptance condition.
- Publish a metric definition sheet and keep its revision history.
- Review a consistent sample of notifications, including night and weekend shifts.
- Validate incident timestamps against monitoring and communication records.
- Choose one coverage gap, one response improvement, and one risk item to address.
- Return next week with evidence of the outcome, not only a closed task.
After four weeks, compare comparable periods and explain changes in traffic, incident mix, and monitoring coverage. Treat the figures as a starting point for investigation. The productive outcome is a better service decision and a verified improvement, not a more attractive scorecard.
References and application notes
Further reading: Google’s Monitoring chapter discusses data freshness, useful visualizations, and views suited to different audiences. The worksheets, examples, and review plans in this guide are proposed practices to adapt to your service.
All numerical scenarios are illustrative. Agree targets, severity definitions, permissions, and response expectations with your service owners before applying them.