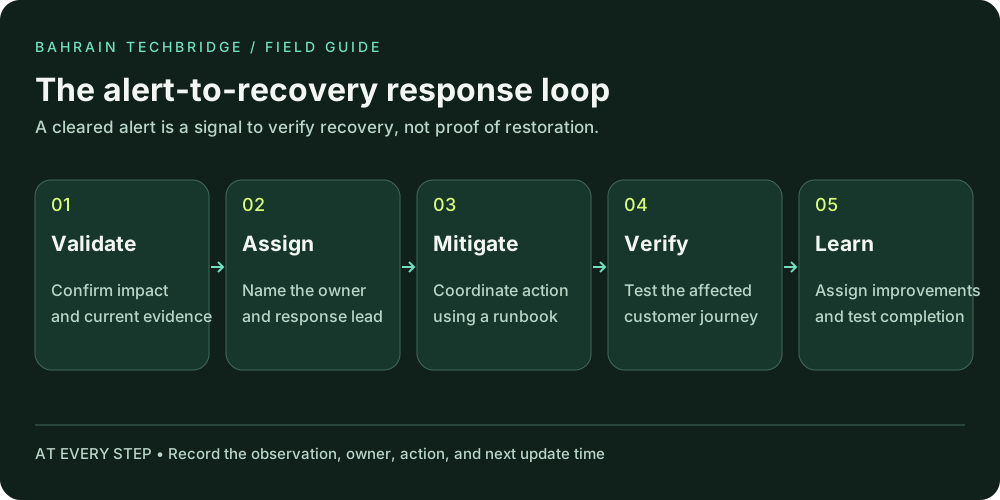
A practical guide to impact-led triage, ownership, escalation, recovery verification, and incident learning. Use this guide with your operations team to identify one improvement, assign an owner, and verify the result.
Define what an alert should make someone do
An alert is useful when it initiates an appropriate response. It should help the receiver establish what changed, why it matters, and which first check to perform. An urgent subject line without an affected service or owner transfers the interpretation burden to the person on call, often at the worst possible moment.
Review alerts from the responder’s perspective. Include the environment, affected service, observed condition, first observed time, severity, evidence link, and relevant runbook. Use a concise title that distinguishes the incident from other events. Keep the full technical detail available through a stable link rather than packing every log line into the notification.
Decide which conditions deserve immediate interruption and which belong in a work queue. A certificate approaching expiry may need planned action; an active customer transaction failure may need an immediate page. Base the route on service impact and urgency, with agreed exceptions for conditions that could rapidly cause harm.
Validate impact and establish ownership
On receipt, confirm that the signal is current and relates to the expected environment. Check whether maintenance or a known incident explains it. Look for independent evidence of impact, such as a synthetic transaction, request failures, or support reports. An isolated infrastructure symptom can be important, but it does not always establish customer impact.
Acknowledge the notification according to your response process, then identify the accountable responder. Acknowledgement means someone has accepted responsibility for the next step; it does not mean that the condition is understood or resolved. If the alert reached the wrong team, transfer ownership explicitly and confirm acceptance rather than dropping a message into another queue.
Create or link an incident record when the situation warrants coordinated response. Deduplicate related notifications into that record without discarding the original evidence. Record the time, observation, and next action. Use one timezone consistently, or include offsets when participants work across regions.
What is affected? Service and customer journey. What is observed? Evidence and timestamp. Who owns the response? Named role or responder. What happens next? One clear investigative or mitigation step. When is the next update? Agreed time and channel.
Set severity using business impact
Agree a severity model before an incident. Consider the number and type of users affected, the importance of the transaction, the availability of a workaround, and how quickly the situation may deteriorate. A high CPU reading alone should not automatically create the organization’s highest severity incident.
Use the following as a discussion template, not a universal standard. Each organization should define its own thresholds, response expectations, and authority to change severity. Keep information-security and safety escalation procedures available where the evidence suggests those concerns; a general operations workflow does not replace specialist response.
| Illustrative level | Impact pattern | Response pattern |
|---|---|---|
| Critical | Critical journey unavailable; no adequate workaround | Activate coordinated response and frequent updates. |
| High | Significant degradation or a substantial user subset affected | Assign a lead and a clear mitigation plan. |
| Standard | Limited impact or an effective workaround | Route to the responsible team with a due time. |
| Advisory | No present impact; preventive action needed | Track planned work and escalation conditions. |
Reassess severity as evidence changes. Document the reason for an upgrade or downgrade so stakeholders understand what changed. Do not lower severity merely because a team is busy or because a notification has been acknowledged.
Coordinate the work before it becomes chaotic
For a major incident, identify a response lead, a technical lead, and a communications owner. A small team may combine roles, but the responsibilities should still be explicit. The response lead coordinates priorities and decisions; technical responders investigate and restore service; the communications owner keeps stakeholders informed.
Establish one response channel and one incident timeline. Ask responders to record significant observations, proposed actions, approvals where required, and results. Multiple people changing the same system without coordination can make cause and effect impossible to distinguish and may prolong recovery.
Set a fallback escalation route if the primary owner does not respond. Define it in advance with the service owner and support organization. The escalation should reach someone empowered to arrange help or make a decision, rather than simply copying more people into a growing email chain.
Use concise updates: current impact, action underway, known limitations, and next update time. If the recovery time is unknown, say so. An unsupported restoration estimate can create unnecessary pressure and distract responders. State the next information checkpoint even when there is no reliable completion estimate.
Use the runbook to choose a safe next step
A runbook should begin with scope and prerequisites, not a list of commands. Explain the symptoms it covers, evidence needed to confirm the scenario, required access, expected results, and conditions that require escalation. Include the owner and last review date so a responder can judge whether the procedure is current.
Prefer an approved mitigation that restores service while preserving evidence. Depending on the system, this may involve rollback, traffic shifting, capacity adjustment, or another established action. These are examples, not instructions to apply blindly. Check the service-specific risks, authority, and rollback path before execution.
Perform one coordinated change at a time where practical and observe its effect. Record the exact action and timestamp. If several actions must run in parallel, assign owners and make the boundaries clear. Stop repeated attempts when the expected result does not appear; looping through the same procedure can consume time and conceal a different failure.
Distinguish mitigation from permanent repair. Restoring a customer journey through a workaround can be a successful incident response even when an engineering fix remains outstanding. Record the workaround’s limitations, monitoring needs, and removal plan so it does not become an undocumented dependency.
Verify restoration from the customer side
Do not close the incident solely because an alert cleared. Verify the affected transaction, error behavior, and relevant service indicators. Check whether request volume returned, because falling traffic can make an error percentage appear healthier. Confirm recovery in the affected regions or customer segments, not only in a convenient test location.
Use an agreed observation period appropriate to the service and failure pattern. There is no single duration that proves every system has recovered. Document who verified restoration, which evidence was checked, and any remaining risk. If a temporary workaround is in place, make that explicit in the final operational update.
10:02 UTC: synthetic submission fails. 10:04: operator confirms customer impact. 10:07: payments team accepts ownership. 10:16: approved rollback starts. 10:24: transaction checks recover. 10:39: agreed observation completes and the service owner accepts restoration. Keep the recovery and verification timestamps separate.
Close the operational loop with service stakeholders. Explain what is restored, what remains under investigation, and where follow-up actions will be tracked. The incident record should be sufficient for the next shift to understand the outcome without replaying the entire response conversation.
Convert the incident into a better response next time
Review significant incidents while evidence is available. Separate confirmed facts, contributing conditions, and unresolved hypotheses. Focus the discussion on how the system and response process behaved, including what helped responders. A useful review should surface missing context, unclear ownership, or a runbook defect as readily as a software bug.
Assign a small number of corrective actions with owners, due dates, and verification criteria. “Improve monitoring” is too broad. “Add a production transaction check for the affected payment route and demonstrate that it reaches the on-call team” is concrete and testable. Track recurring incidents against these actions to see whether the intended improvement occurred.
- Compare onset, detection, acknowledgement, mitigation, and verified restoration.
- Identify the longest avoidable wait and the decision that could shorten it.
- Update the alert payload and runbook using actual responder questions.
- Practice the revised procedure in a controlled exercise.
- Close corrective actions only after reviewing evidence of completion.
A productive response process connects a signal to a person, a decision, and verified service recovery. Strengthen that connection for one recurring incident type first, then use the lessons to improve the broader service delivery process.
References and application notes
Further reading: Google’s Incident Response describes structured coordination, while Postmortem Culture discusses learning from incidents. The worksheet and example severity model here are starting points to adapt to your organization.
All numerical scenarios are illustrative. Agree targets, severity definitions, permissions, and response expectations with your service owners before applying them.