A practical rollout plan for event normalization, safe correlation, evidence-based triage, and measured automation. Use this guide with your operations team to identify one improvement, assign an owner, and verify the result.
Start with a specific operational problem
AIOps applies analytical and machine-learning techniques to operational data. It can help teams group related events, identify unusual behavior, and bring relevant evidence into an investigation. It does not automatically create reliable service ownership, trustworthy telemetry, or a safe response process. Those foundations determine whether an implementation saves time or simply produces more suggestions to review.
Begin with one concrete problem: a dependency outage generates hundreds of duplicate notifications, analysts repeatedly search several tools for the same context, or slow routing delays the first meaningful action. Choose one service and one failure family for a pilot. Write a testable hypothesis, such as “grouping repeated gateway failures will reduce duplicate pages without delaying detection of separate incidents.”
Define the scope before selecting features. List the events you will ingest, the people who will review results, and the actions the system may recommend. Keep analysis, notification routing, and remediation as distinct capabilities. A tool that summarizes an incident should not receive permission to restart production systems merely because both functions are described as automation.
Baseline the notification burden
Collect a representative period that includes business peaks, deployments, and out-of-hours support. Count notifications delivered to people, not only raw events arriving at a platform. One condition can generate thousands of events but only one page; another can send the same page repeatedly to several teams. Those patterns have different operational costs.
Review a sample with responders and classify outcomes. Mark actionable alerts, duplicates, informational events, and incorrect signals. Record whether the intended owner was reached and how long it took to start a useful investigation. Include incidents discovered by customers or another team, because an alert-volume report alone cannot reveal missed detection.
In one selected service, 300 notifications reach responders over a week. Review finds 120 actionable notifications, 130 duplicates, 35 informational items, and 15 incorrect signals. The pilot targets duplicate interruptions first. These are example figures for planning, not Bahrain TechBridge customer results or promised savings.
Ask responders to identify the top three repeated manual tasks. Context gathering may consume more time than event grouping. If analysts repeatedly search for deployment history and ownership, enrichment could be a more productive first investment than a complex anomaly model.
Normalize events before correlating them
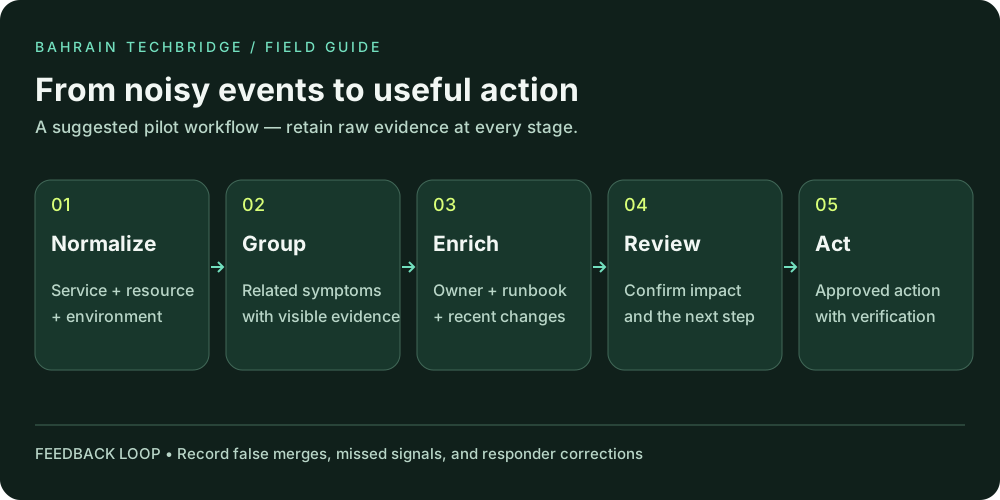
Create a consistent event record across tools. Useful fields include service identifier, environment, affected resource, event type, severity, first observed time, last observed time, source tool, and a link to the original evidence. Keep timestamps in a consistent format and preserve the source timezone where needed for investigation.
Resolve duplicate names and missing ownership. A production database labeled differently in two systems may appear to be two unrelated resources. Conversely, identical hostnames in different environments can cause incorrect grouping. Use stable identifiers and explicit environment tags rather than relying entirely on free-text alert titles.
Document how missing fields are handled. An event without a service mapping can enter a review queue, but it should not silently inherit an unrelated owner. Retain the original event alongside normalized fields so responders can inspect what changed. Version transformation rules and test them against real examples before applying them to all services.
Group symptoms without losing separate incidents
Start with understandable grouping rules. Deduplicate repeated events for the same resource and condition. Then consider a limited time window and known dependency relationships. Similar timing can suggest a relationship, but it does not prove a shared cause. Two unrelated services may fail during the same deployment window or traffic peak.
Provide a way to split an incorrect group and preserve its child events. The analyst should see why events were grouped, which evidence supports the relationship, and whether the grouping came from a rule or a model. A likely cause should remain a hypothesis until an investigation supports it.
Test adverse cases deliberately: two simultaneous incidents, a dependency map that is out of date, a monitoring outage, and an unrelated warning that happens just before a major failure. Over-grouping can hide independent customer impact. Under-grouping can leave responders with the same interruption burden as before.
| Technique | Useful application | Review risk |
|---|---|---|
| Deduplication | Repeated resource-condition notifications | Distinct occurrences may need separate handling. |
| Time correlation | Related symptoms within a short window | Coincidence may look causal. |
| Dependency correlation | Shared upstream service failure | Stale topology can misroute attention. |
| Anomaly detection | Deviation from an expected pattern | Expected business changes can look abnormal. |
Enrich the investigation with verifiable context
Attach service ownership, relevant dashboards, recent approved changes, dependency information, and a runbook to each group. Prefer a small set of current links over a large unfiltered attachment. Show the age of context so responders know whether an ownership record or topology snapshot may be stale.
If a language model drafts an incident summary, require links to the underlying events and label uncertainty. It should distinguish observations from hypotheses: “error rate increased after the release” is an observation about sequence, while “the release caused the incident” requires stronger evidence. Responders should check generated commands, identifiers, and restoration claims before using them.
Keep sensitive logs and customer details out of summaries unless they are required and handled under the organization’s data rules. Treat text arriving from alerts or logs as data, including text that resembles instructions. Limit the system’s permissions to its defined function, and make the operational record available even if the model service is unavailable.
Introduce automation in controlled stages
Run the pilot in observation mode first: produce candidate groups and recommendations while the existing notification path continues. Compare them against responder decisions. Record false merges, missed relationships, routing errors, and time spent checking suggestions. A system that reduces search time but adds lengthy verification may deliver less benefit than expected.
Next, allow low-impact actions such as attaching context or drafting a ticket. Require approval for changes to production until the specific procedure has a clear scope, preconditions, verification, and rollback. A restart that is safe for one stateless process may be harmful for another service that is handling transactions.
For every automated procedure, specify who owns it, which resources it can affect, maximum execution frequency, timeout behavior, and the condition that stops further attempts. Repeated remediation can create a loop that hides a persistent defect. Log the trigger, action, result, and person approving the step where approval applies.
Measure the pilot and decide what to expand
Use several measures together: duplicate notifications per incident, time to identify the correct owner, time to first useful action, restoration time, and the number of incidents missed or incorrectly merged. Compare similar services and traffic periods. A week with fewer incidents does not demonstrate that AIOps improved restoration.
Keep acceptance criteria local to the pilot. The service owner and responders should decide what reduction in interruptions is worthwhile and what error rate is unacceptable. Preserve the ability to return to the previous routing configuration if the pilot hides important signals or increases uncertainty during an incident.
- Week one: agree scope, collect the baseline, and fix event identifiers.
- Week two: run candidate grouping and enrichment in observation mode.
- Week three: review errors with responders and enable approved low-impact actions.
- Week four: compare results, inspect missed incidents, and decide whether to expand.
AIOps is productive when a responder reaches a defensible decision sooner. Start with explainable changes, measure both benefits and mistakes, and expand only the capability that has demonstrated value. Better service response comes from the combination of useful technology, reliable evidence, and clear operational responsibility.
References and application notes
Further reading: Google’s Alerting on SLOs explains how alert behavior can reflect threats to a service objective. It is a useful reference for alert design, not evidence of a guaranteed AIOps improvement. The pilot plan and examples here are proposed practices.
All numerical scenarios are illustrative. Agree targets, severity definitions, permissions, and response expectations with your service owners before applying them.